↔
Deployment freedom
Design around on-premises, private cloud, public cloud and hybrid operating needs, with explicit profiles and support boundaries.
S.A.N.A.T.A.N brings infrastructure automation, data engineering, analytics, AI and application operations into one composable stack—designed for on-premises, private cloud, public cloud and hybrid environments.
S.A.N.A.T.A.N connects deployment automation, centralized administration, access governance and platform intelligence around a composable technology stack. Each named component has a distinct responsibility; the architecture map below explains how the technical domains fit together.
Design around on-premises, private cloud, public cloud and hybrid operating needs, with explicit profiles and support boundaries.
Combine focused components across ingestion, processing, storage, governance, analytics and AI.
S.E.T.U. is the unified user interaction and access concept across the stack, with role-based controls as a central design requirement.
M.A.T.S.Y.A., V.A.M.A.N.A. and M.A.Y.A.D.H.I represent infrastructure provisioning, deployment and cross-workflow coordination.
S.A.R.A.S.W.A.T.I. is the optional, on-demand Platform RAG Support concept based on LangGraph + CrewAI, with controlled execution boundaries.
Separate component inclusion from integration, deployment testing, production operation and resilience evidence.
Use the architecture domains to understand how the layers connect. The comparison matrix translates these domains into industry-recognizable requirements and representative alternatives.
Provision and operate the environments that host the stack.
Ingest source data, stream events and run batch or streaming workloads.
Build repeatable transformations, scheduled workflows and data validation.
Match storage engines and formats to transactional, analytical and graph workloads.
Explore data, build models and support feature engineering, serving and retrieval.
Deliver applications through CI/CD and manage visibility, identity and recovery.
Cross-cutting control plane: S.E.T.U. access, authorization, audit and operational guardrails span across the platform. S.A.R.A.S.W.A.T.I. may retrieve and synthesize platform knowledge to assist a deployment workflow, doesnt bypass authorization, policy checks, approvals or validated execution controls.
Compare S.A.N.A.T.A.N against Databricks, Snowflake, AWS, Google Cloud, Microsoft Azure and Palantir across the architecture requirements that matter. This is a capability map, not a claim that unlike delivery models are identical.
Seven platform columns. Infrastructure through data, AI, CI/CD, serverless, operations and economics. Use the detailed matrix for evidence states and validation notes.
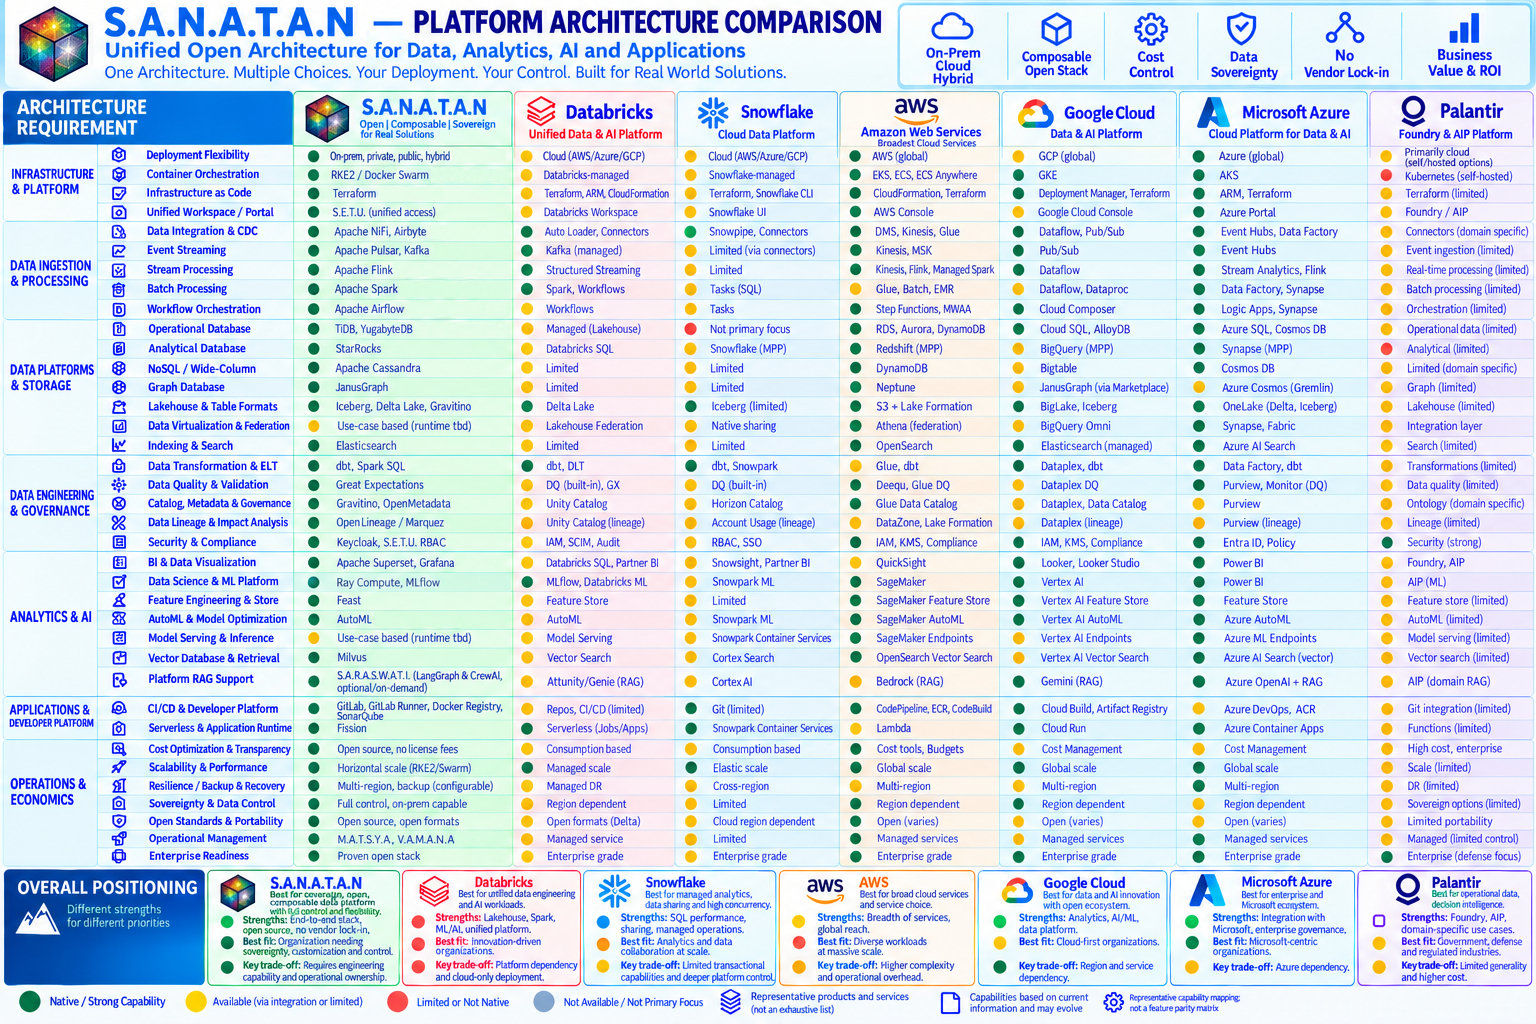
Representative services and products are examples, not an exhaustive inventory. Cloud-managed services and self-managed open-source components have different operational boundaries. Verify current capabilities, supported regions and licensing before procurement decisions.
The map follows every architecture requirement named in the platform comparison image. Search by product, capability, acronym or domain; use the requirement selector to jump directly to a row. This index is also intended to be useful when visitors arrive looking for a specific technology.
| Architecture requirement | Representative alternatives & ecosystem terms | S.A.N.A.T.A.N mapping / scope |
|---|---|---|
| Deployment FlexibilityInfrastructure & Platform | On-premises; private cloud; public cloud; hybrid | On-premises, private cloud, public cloud and hybrid deployment profiles |
| Container OrchestrationInfrastructure & Platform | RKE2; Docker Swarm; Kubernetes; EKS; ECS; GKE; AKS | V.A.M.A.N.A. deployment workflows for RKE2 and Docker Swarm |
| Infrastructure as CodeInfrastructure & Platform | Terraform; ARM templates; CloudFormation; Deployment Manager | M.A.T.S.Y.A. — Terraform-based infrastructure provisioning |
| Unified Workspace / PortalInfrastructure & Platform | Databricks Workspace; Snowflake UI; AWS Console; Google Cloud Console; Azure Portal; Foundry / AIP | S.E.T.U. — unified user interaction and access concept |
| Data Integration & CDCData Ingestion & Processing | Apache NiFi; Airbyte; Auto Loader; Snowpipe; DMS; Kinesis; Glue; Dataflow; Pub/Sub; Event Hubs; Data Factory | Apache NiFi; Airbyte |
| Event StreamingData Ingestion & Processing | Apache Pulsar; Kafka; managed Kafka; Kinesis / MSK; Pub/Sub; Event Hubs | Apache Kafka; Apache Pulsar |
| Stream ProcessingData Ingestion & Processing | Apache Flink; Spark Structured Streaming; Kinesis Data Analytics; Dataflow; Stream Analytics | Apache Flink; Spark streaming capabilities |
| Batch ProcessingData Ingestion & Processing | Apache Spark; Databricks jobs; AWS Glue / Batch / EMR; Dataproc; Data Factory / Synapse | Apache Spark |
| Workflow OrchestrationData Ingestion & Processing | Apache Airflow; Databricks Workflows; Snowflake Tasks; Step Functions / MWAA; Cloud Composer; Logic Apps / Synapse | Apache Airflow; M.A.Y.A.D.H.I. workflow coordination |
| Operational DatabaseData Platforms & Storage | TiDB; YugabyteDB; managed SQL; RDS; Aurora; DynamoDB; Cloud SQL; AlloyDB; Azure SQL; Cosmos DB | TiDB; YugabyteDB; Cassandra and relational services where configured |
| Analytical DatabaseData Platforms & Storage | StarRocks; Databricks SQL; Snowflake MPP; Redshift; BigQuery; Synapse | StarRocks |
| NoSQL / Wide-ColumnData Platforms & Storage | Apache Cassandra; DynamoDB; Bigtable; Cosmos DB | Apache Cassandra |
| Graph DatabaseData Platforms & Storage | JanusGraph; Neptune; Cosmos DB Gremlin | JanusGraph |
| Lakehouse & Table FormatsData Platforms & Storage | Apache Iceberg; Delta Lake; Gravitino; Unity Catalog; Lake Formation; BigLake; Fabric / OneLake | Apache Iceberg; Delta Lake; Gravitino; Spark |
| Data Virtualization & FederationData Platforms & Storage | Lakehouse Federation; Snowflake sharing; Athena federation; BigQuery Omni; Synapse / Fabric integration | Use-case based; runtime federation capability should be mapped per supported connector |
| Indexing & SearchData Platforms & Storage | Elasticsearch; OpenSearch; managed Elasticsearch; Azure AI Search | Elasticsearch |
| Data Transformation & ELTData Engineering & Governance | dbt; Spark SQL; Snowpark; AWS Glue; Dataplex; Azure Data Factory | dbt; Spark SQL |
| Data Quality & ValidationData Engineering & Governance | Great Expectations; built-in quality checks; Deequ; Dataplex DQ; Purview / Monitor | Great Expectations |
| Catalog, Metadata & GovernanceData Engineering & Governance | Gravitino; OpenMetadata; Unity Catalog; Horizon Catalog; Glue Data Catalog; Dataplex; Purview; Palantir Ontology | Gravitino; OpenMetadata; Unity Catalog where configured |
| Data Lineage & Impact AnalysisData Engineering & Governance | OpenLineage / Marquez; Unity Catalog lineage; Snowflake Account Usage; DataZone / Lake Formation; Dataplex; Purview | OpenLineage / Marquez; lineage integration mapped by workload |
| Security & ComplianceData Engineering & Governance | Keycloak; SETU RBAC; IAM; Secrets Manager; KMS; compliance controls; Entra ID; policy controls | K.U.R.M.A. centralized ACL/RBAC; S.E.T.U.; Keycloak; N.A.R.A.S.I.M.H.A. security controls |
| Data VisualizationAnalytics & AI | Apache Superset; Grafana; Databricks SQL Partner Connect; Snowsight; QuickSight; Looker; Power BI; Foundry / AIP | Apache Superset; Grafana |
| Data Science & ML PlatformAnalytics & AI | Spark ML; MLflow; Ray; Databricks ML; Snowpark ML; SageMaker; Vertex AI; Azure ML | Ray Compute; MLflow |
| Feature Engineering & StoreAnalytics & AI | Feast; managed feature stores; SageMaker Feature Store; Vertex AI Feature Store; Azure Feature Store | Feast |
| AutoML & Model OptimizationAnalytics & AI | AutoML; Snowpark ML; SageMaker AutoML; Vertex AI AutoML; Azure AutoML | AutoML capability |
| Model Serving & InferenceAnalytics & AI | Model serving; Snowpark Container Services; SageMaker Endpoints; Vertex AI Endpoints; Azure ML Endpoints | Use-case based; document the selected runtime and endpoint pattern |
| Vector Database & RetrievalAnalytics & AI | Milvus; Databricks Vector Search; Cortex Search; OpenSearch vector; Vertex AI Vector Search; Azure AI Search | Milvus |
| Platform RAG SupportAnalytics & AI | S.A.R.A.S.W.A.T.I.; LangGraph; CrewAI; Bedrock RAG; Gemini RAG; Azure OpenAI + RAG; Palantir AIP | S.A.R.A.S.W.A.T.I. — optional on-demand platform RAG assistance using LangGraph + CrewAI |
| CI/CD & Developer PlatformApplications & Developer Platform | GitLab; GitLab Runner; private Docker Registry; SonarQube; CodePipeline; ECR; CodeBuild; Cloud Build; Artifact Registry; Azure DevOps; ACR | GitLab; GitLab Runner; private Docker Registry; SonarQube |
| Serverless & Application RuntimeApplications & Developer Platform | Fission; serverless jobs/apps; Snowpark Container Services; AWS Lambda; Cloud Run; Azure Container Apps / Functions | Fission |
| Cost Optimization & TransparencyOperations & Economics | Open-source/no license fees; consumption pricing; cloud cost tools; budgets; Cost Management | Open-source components and self-managed deployment can reduce license dependence; total cost depends on operations |
| Scalability & PerformanceOperations & Economics | Horizontal RKE2/Swarm scale; managed scale; elastic/global cloud scale | RKE2 / Docker Swarm deployment profiles; component-specific scale patterns |
| Resilience, Backup & RecoveryOperations & Economics | Multi-region backup; managed DR; cross-region recovery; cloud backup services | Recovery strategy is deployment-profile dependent; document tested backup/restore and RPO/RTO |
| Sovereignty & Data ControlOperations & Economics | On-prem control; region-dependent cloud controls; sovereign cloud options | On-premises-capable composable stack; actual sovereignty depends on chosen topology and operations |
| Open Standards & PortabilityOperations & Economics | Open formats; cloud-specific services; open-source components; portability limits | Open components and formats where supported; portability varies by integration |
| Operational ManagementOperations & Economics | M.A.T.S.Y.A.; V.A.M.A.N.A.; managed services; cloud operations consoles | M.A.T.S.Y.A.; V.A.M.A.N.A.; M.A.Y.A.D.H.I.; D.E.V.I. administrator dashboard |
| Enterprise ReadinessOperations & Economics | Enterprise-grade managed platforms; Palantir enterprise/domain focus | Composable platform initiative; readiness must be evaluated against documented integration, security, support and recovery evidence |
The alternatives column records representative terms shown in the comparison graphic and related implementation choices; it is not an exhaustive vendor service catalogue. A named mapping indicates architecture scope, not automatic proof of feature parity.
These named components form the administration, orchestration, security and intelligence layer around the underlying tools. Each has a defined job and a practical operating benefit.
A unified operational dashboard for synchronizing deployments and bringing stack-wide administration into one interface.
A tools-version management interface that lets system administrators control approved versions without waiting for a S.A.N.A.T.A.N-led release.
Coordinates platform and application workflows across the S.A.N.A.T.A.N operating model.
Provides infrastructure provisioning workflows for the environments in which the stack is intended to run.
Centralized user and access-control management across product segments, with consistent ACL and RBAC policy as the goal.
A cross-stack security concept centered on authenticated secure channels and limiting the blast radius of compromise.
Manages deployment workflows for applications and supported cluster environments, including RKE2 and Docker Swarm.
The unified user interaction endpoint and central access point for working across the platform.
On-demand platform RAG support using LangGraph and CrewAI concepts to help users reason about platform knowledge and deployment workflows.
Enterprise solutions mandate evaluated breadth, supported deployment profiles, operational evidence, security posture, recovery procedures and a credible maintenance model.
Named in the stack inventory or confirmed as part of the intended stack.
Install from a clean environment with documented versions and prerequisites.
Validate data paths, auth, failure handling, observability and upgrades.
Publish repeatable demos, runbooks, restore tests and known limitations.
Launch discipline: before broad production-readiness claims, resolve source secrets, authentication/session lifecycle, dynamic SQL/shell execution risks, least privilege, third-party licensing, backup/restore and disaster-recovery evidence. The public story is strongest when implementation and claims agree.
Review the capability map, inspect the release manifest, and follow the Getting Started steps to pull the S.A.N.A.T.A.N image and prepare your first deployment.